Databricks Genie One: The Skill Multiplier


Let me describe a problem I’ve lived with for years, and then show you what’s now possible.
In onshore unconventional oil and gas, the field development plan is the single largest capital decision an operator makes. Well count, spacing, sequencing, completion design — these choices commit nine figures of capital against deep uncertainty.
Here’s how that decision gets made today:
The reservoir engineer pulls simulation outputs from one system. The drilling team has their well inventory and cost estimates in another. Facility engineering has surface constraints in a third. The economics team runs NPV and break-even in a spreadsheet that nobody else can audit. And the pricing assumptions? Those came from an email last Tuesday.
Five disciplines. Five systems. Five versions of the truth.
The person making the capital allocation decision — the VP of Development — sees a PowerPoint that stitched it all together manually. By the time it reaches them, the assumptions are already stale.
I’ve spent a career watching this play out. And the constraint was never intelligence. The engineers are brilliant. The constraint was that the systems they work in enforce boundaries between disciplines. The reservoir engineer can’t see the facility data. The economist can’t see the subsurface risk. The drilling team can’t see the pricing sensitivity.
Not because they lack curiosity. Because the data lives in different places, governed by different teams, with no single surface that lets one person reason across all of it at once.
What’s now possible with Databricks Genie One
Databricks Genie One changes this — with an important constraint I’ll be upfront about.
Genie One is a natural language interface built on Databricks Unity Catalog. It searches across Genie Agents, dashboards, queries, and metric views to answer questions — generating governed, read-only SQL and routing to the most relevant domain-specific agent when a match exists. You can also connect external document sources like Google Drive and SharePoint. Every answer includes citations and the generated SQL is visible, so results are traceable to specific tables and columns. And every query runs under the asking user’s own Unity Catalog permissions — the development engineer sees the economics, the JV partner sees their working interest share and nothing else, provided you’ve configured the appropriate row and column-level security policies.
The constraint: Genie One is only as good as the data you bring into the Databricks ecosystem — and the Genie Agents, dashboards, and metric views you configure on top of it. If your reservoir simulation outputs, well inventory, facility engineering data, service cost history, and economic models aren’t registered in Unity Catalog with discoverable analytics surfaces, Genie One can’t reason across them. The data integration and curation work is real. It’s not trivial. But once that data is there — governed, cataloged, and permission-aware — something genuinely new becomes possible.
Here’s what that looks like.
A development engineer could type a question like this into Databricks Genie One:
“I’m evaluating infill development options for our Wolfcamp A acreage in the Midland Basin. Pull the current drillable well inventory for Sections 12 through 18 — lateral lengths, target formations, and spacing assumptions. Cross-reference against the latest reservoir simulation: remaining recoverable reserves by bench, pressure depletion maps, and parent-child well interference risk where we have offset producers within 660 feet.
Then pull facility engineering constraints: available surface locations, gathering system capacity at the central delivery point, and any compression or water handling bottlenecks that would limit a simultaneous 4-well pad development. Layer in current service costs — rig day rates, completion spread costs, and sand pricing from our last three AFEs in this area.
Run the economics: NPV10 and break-even oil price for a 4-well pad at $68 WTI, with sensitivities at $58 and $78. Compare against a 2-well staggered program. Show me which scenario maximizes capital efficiency per BOE added, and flag any subsurface or surface risks that could blow the economics by more than 15%.”
One prompt. Five domains. The kind of question that currently takes four teams, three meetings, and two weeks to assemble manually.
Genie One handles this by routing to the most relevant Genie Agent, generating governed SQL against Unity Catalog tables, and returning the answer with the source SQL visible for verification. For questions that span multiple domains, a Supervisor Agent pattern can orchestrate across specialist Genie Agents — subsurface, economics, drilling, facility engineering — composing a unified answer. The economics can run through SQL functions registered in Unity Catalog — auditable, version-controlled, and shared across teams — rather than a spreadsheet that nobody else can audit. What used to take two weeks of cross-team coordination can now happen in a single analytical session.
The skill multiplier effect
Here’s the part I care about most — and the reason I’m writing this as a practitioner, not a marketer.
The interesting thing about that prompt isn’t the speed. It’s what it does to the person asking it.
A reservoir engineer who types that question is no longer operating within a single discipline. They’re integrating subsurface uncertainty, drilling execution risk, facility constraints, service cost volatility, and economic sensitivity — in a single analytical session. They’re thinking across boundaries that used to be walls.
Imagine the facility constraints show up in the same answer as the reservoir simulation. The engineer notices that the gathering system capacity at the central delivery point can’t handle a simultaneous 4-well completion. That’s not their domain. They’d never have known to ask. But now they see it, and they adjust the plan. The 2-well staggered program — which looked worse on paper — actually maximizes capital efficiency once you factor in the surface bottleneck.
That engineer didn’t go back to school. They didn’t get a second degree in facility engineering. Databricks Genie One expanded the boundary of what they could reason about.
That’s not outsourcing your thinking to a machine. That’s developing new thinking with one.
Get Abhay Singh’s stories in your inbox
Join Medium for free to get updates from this writer.
This isn’t just for engineers
I used a technical example because it’s the world I work in. But here’s what I want to be clear about: Databricks Genie One is built for business users, not just specialists.
The VP of Development who used to wait two weeks for that PowerPoint? They can now ask the question directly — in plain language, no SQL, no technical setup. They get the same governed, traceable answer the engineer gets, scoped to exactly what they’re authorized to see.
The finance lead who never touched reservoir data can now ask: “What’s our break-even exposure if service costs rise 12% and WTI drops to $58?” — and get an answer grounded in the actual well economics and simulation outputs, not a summary someone prepared for them.
The operations manager can ask about production decline patterns across a fleet of wells and get a diagnosis — mechanical vs. reservoir-driven — without waiting for the surveillance team to run the analysis.
None of these people write SQL. None of them need to. Databricks Genie One generates the governed queries, routes to the right specialist agents, and returns the answer in natural language with the data behind it.
That’s the deeper point about the skill multiplier. It doesn’t just widen the specialist’s lens. It dissolves the barrier between “technical user” and “business user” entirely. The question is the interface. If you can articulate what you need to know, Genie One can reason across the governed data to answer it.
The skill that gets multiplied isn’t a technical skill. It’s the ability to think across domains — and that belongs to everyone in the organization who makes decisions.
Co-intelligence, not automation
There’s a narrative in the market right now that AI replaces human judgment. That the goal is to automate the analyst, the engineer, the decision-maker.
I think that’s exactly wrong — at least for the kind of high-stakes decisions I work with.
What Databricks Genie One enables isn’t replacement. It’s amplification. The engineer does more thinking, not less. They integrate more variables, not fewer. They make a better decision because they can finally see the full picture — not because a machine made the decision for them.
This is what co-intelligence looks like in practice. The machine handles the data retrieval, the cross-referencing, the computation across five systems. The human does what humans do: notices the anomaly, questions the assumption, changes the plan.
The machine surfaces the data. The human makes the call.
That’s not automation. That’s acceleration — of the person, not just the process.
Why grounding in governed data is the difference
General-purpose AI chatbots are extraordinary at language. I use them daily. But when I need to support a capital allocation decision on a $200M development program, I need something different.
I need the answer to come from my data — not the internet’s. I need every number traceable to a specific table and column, with the SQL visible for verification. I need the metric definitions to be the ones my company certified, not the ones a model learned from public training data. I need the answer to respect who should see what.
Most AI chatbots can connect to internal data sources now. That’s table stakes. But connection isn’t governance. Pulling data from a database isn’t the same as knowing which definition of “remaining recoverable reserves” is the certified one, or understanding that your reservoir team and your economics team use the same term to mean different things.
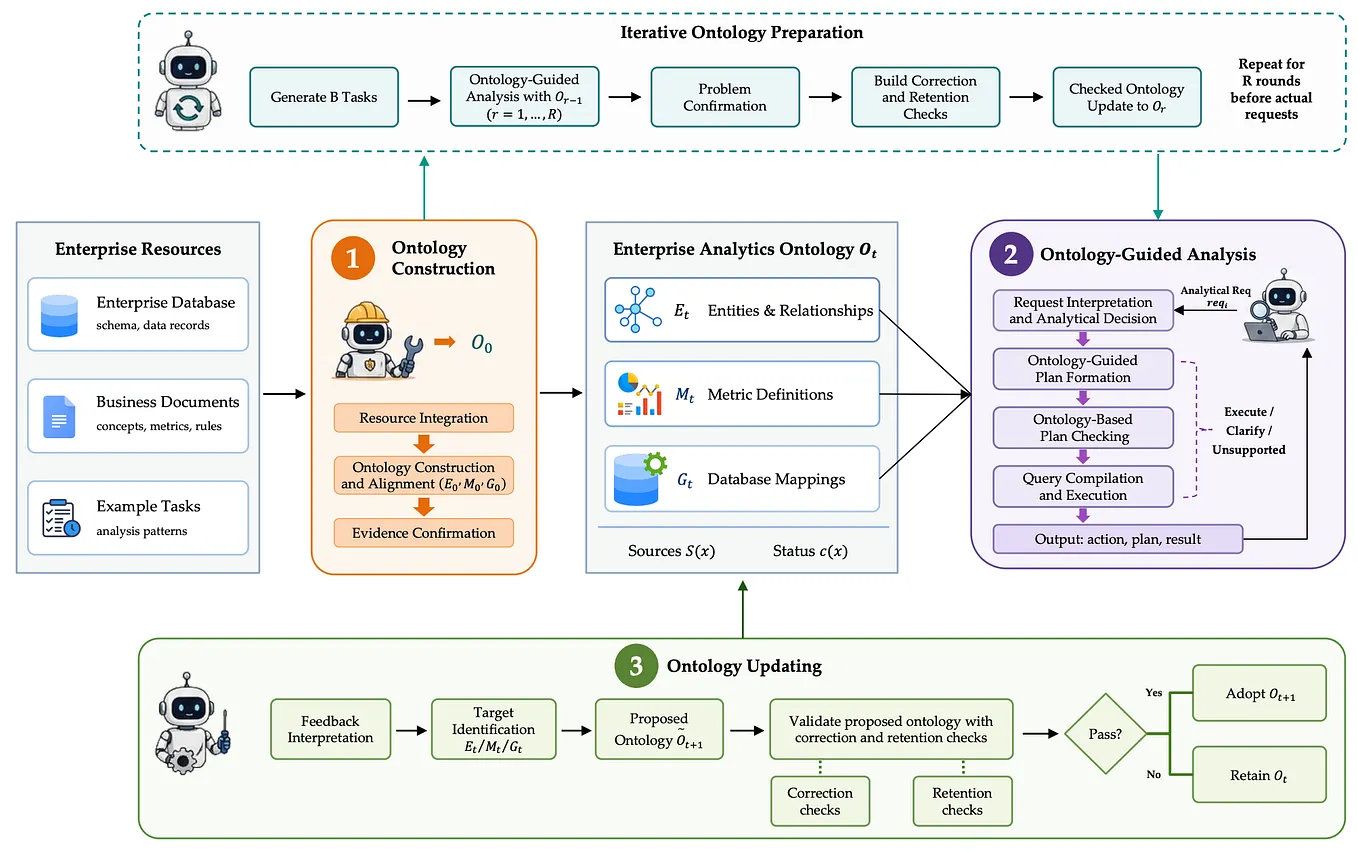
Databricks Genie One closes that gap through the Genie Ontology — an auto-generated context layer that learns your metric definitions, your business vocabulary, and your authoritative data sources from your actual tables, dashboards, and pipelines. It resolves conflicting definitions and ranks by authority. Internal benchmarks show accuracy improving from roughly 60% to over 84% with Ontology enabled.
That’s not a language capability. That’s an institutional knowledge capability. And it only works because the data is governed in Unity Catalog — not scattered across the internet.
What this means for your organization
Every company has smart people trapped in narrow lanes. Not because they lack curiosity — because the systems they work in enforce boundaries.
When you bring your data into the Databricks ecosystem, govern it in Unity Catalog, and put Databricks Genie One in front of your domain professionals, you don’t just get faster answers.
You get people who think bigger because they can finally see bigger.
The reservoir engineer starts thinking about facility bottlenecks. The drilling engineer starts asking about parent-child interference. The economist starts questioning spacing assumptions. Not because they were told to — because the data is right there, in the same answer, for the first time.
The economic output follows. Not because the AI is producing it — because your people are. With a wider lens, a deeper context, and the confidence that comes from knowing every number is traceable, governed, and real.
That’s the skill multiplier.
It’s not about the machine getting smarter. It’s about your people getting wider.