Member-only story
DINOv3 Paper Explained: The Computer Vision Foundation Model

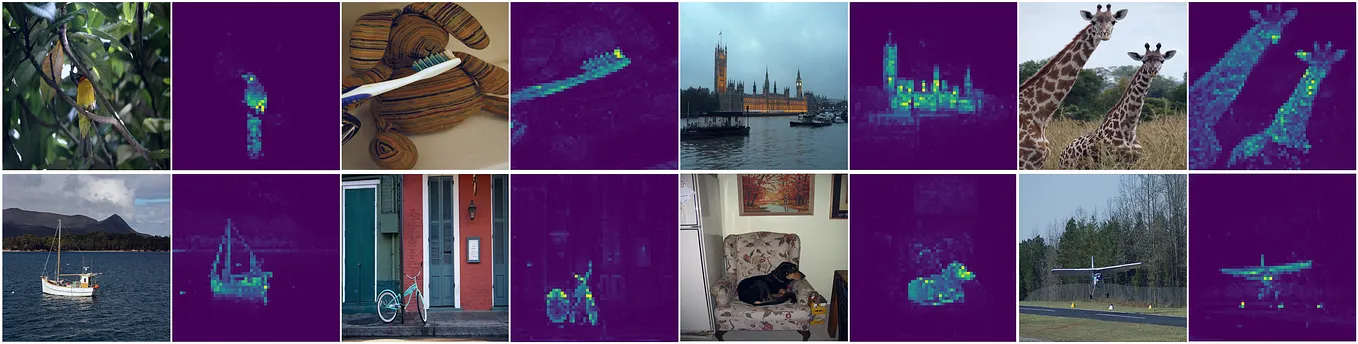
In this post, we break down Meta AI’s DINOv3 research paper, the latest in their open-source family of computer vision foundation models, now achieving state-of-the-art results with a frozen backbone on many benchmarks.
Not a member? Read here.
Introduction
Just as we have large language models (LLMs) serving as general-purpose foundation models for natural language processing (NLP), computer vision is following a similar path with foundation models that can be reused across many tasks. One of the most widely adopted in the past two years has been Meta AI’s DINOv2, which has become one of the go-to backbones in the community.
Now, Meta AI has released the next step in this family: DINOv3. Much like what we’ve seen with LLMs, DINOv3 is both larger and trained on more data, expanding from 1 billion to 7 billion parameters, and from 142 million images to 1.7 billion images.
More parameters, more data. But scaling to this level also introduces new challenges, and some fascinating solutions, which we’ll explore in this post. Specifically, at the end we’ll dive into one of the key innovations that makes DINOv3 work — a method called Gram…