Building a Kubernetes Platform from Scratch (Part 3: GitOps Repository Design and Platform Workloads)

In the first article of this series, I focused on building the Kubernetes foundation. Starting with two Proxmox hosts, I designed the platform architecture and used Ansible to deploy a highly available RKE2 cluster running entirely on self-managed infrastructure.
In the second article, I introduced centralized secret management using Azure Key Vault and deployed External Secrets Operator and Argo CD. At that point, the cluster had all the core building blocks required for a modern platform: Kubernetes, GitOps, and centralized secret management.
However, installing Argo CD is only the beginning. The real challenge is defining how infrastructure, platform services, monitoring, and application workloads are organized, deployed, and managed over time. As the number of services grows, a GitOps repository can quickly become difficult to maintain without a clear structure and deployment strategy.
In this article, I’ll focus on the GitOps architecture that powers the platform. I’ll explain how I organize the repository using the Apps-of-Apps pattern, Argo CD Projects, and Sync Waves to create clear boundaries between infrastructure, platform services, monitoring, and applications. The repository is structured around dedicated workload layers such as 10-infra, 15-platform, 20-monitoring, and 30-apps, each managed by its own Argo CD root application.
Once the GitOps structure is in place, I’ll start deploying the first production workloads through Argo CD. This includes infrastructure services such as cert-manager, MetalLB, Traefik, ExternalDNS, Longhorn, Velero, Rancher, and Cloudflared, followed by platform services including Homepage, Authentik, Wiki.js, and GitLab Runner.
By the end of this article, the platform will be fully managed through GitOps. New infrastructure components, platform services, and applications can be deployed by committing changes to Git, with Argo CD continuously reconciling the desired state of the cluster.

The whole code for this article is avaliable here.
Connecting Argo CD to the GitOps Repository
In the previous article, I installed Argo CD and connected it to Azure Key Vault through External Secrets Operator, but I didn’t explain how to connect it to the GitLab instance. Before Argo CD can deploy anything it first needs access to the Git repository that contains the desired state of the platform.
The first step is creating a dedicated service account for Argo CD in GitLab.

After creating the service account, add it as a member of the GitOps repository with read access permissions.

I prefer using a dedicated account rather than personal credentials because repository access becomes independent of individual users and can be rotated without affecting platform administrators.
The service account only requires read access to the GitOps repository. After creating the account, I generated a Personal Access Token and stored both the username and token in Azure Key Vault:
argocd-gitlab-username
argocd-gitlab-token
Since I already knew that Authentik would become the central identity provider for the platform, I also prepared the future OIDC integration at this stage. The Authentik OIDC client credentials were generated and added to Azure Key Vault even though Authentik itself had not yet been deployed:
argocd-authentik-client-id
argocd-authentik-client-secret
The OIDC client will be later created inside Authentik, but I had already reserved the corresponding secret names in Azure Key Vault to avoid changing the Argo CD configuration later.
Finally, I stored the initial Argo CD administrator password hash. Unlike most applications where a plaintext password is provided and hashed internally, Argo CD expects the bcrypt hash itself inside the secret.
argocd-admin-password-bcrypthashThe resulting Azure Key Vault entries looked as follows:
argocd-admin-password-bcrypthash
argocd-gitlab-username
argocd-gitlab-token
argocd-authentik-client-id
argocd-authentik-client-secret
The following variables map Azure Key Vault secret names to the Argo CD Ansible deployment:
akv_argocd_admin_password_key: argocd-admin-password-bcrypthash
akv_gitlab_username_key: argocd-gitlab-username
akv_gitlab_token_key: argocd-gitlab-token
akv_authentik_client_id_key: argocd-authentik-client-id
akv_authentik_client_secret_key: argocd-authentik-client-secret
Instead of creating repository credentials manually through the Argo CD UI, the playbook (number 15 here) uses External Secrets Operator to retrieve the GitLab username and token from Azure Key Vault and generate a repository secret automatically:
- name: Create ExternalSecret for argocd-secret
      kubernetes.core.k8s:
        kubeconfig: "{{ rke2_kubeconfig }}"
        state: present
        definition:
          apiVersion: external-secrets.io/v1
          kind: ExternalSecret
          metadata:
            name: argocd-secret
            namespace: "{{ argocd_namespace }}"
          spec:
            refreshInterval: 5m

            secretStoreRef:
              kind: ClusterSecretStore
              name: "{{ eso_cluster_secret_store_name }}"

            target:
              name: argocd-secret
              creationPolicy: Merge

            data:
              - secretKey: admin.password
                remoteRef:
                  key: "{{ akv_argocd_admin_password_key }}"

              - secretKey: dex.authentik.clientId
                remoteRef:
                  key: "{{ akv_authentik_client_id_key }}"

              - secretKey: dex.authentik.clientSecret
                remoteRef:
                  key: "{{ akv_authentik_client_secret_key }}"
At the same time, another ExternalSecret populates the main argocd-secret object. Besides the administrator password, it also provisions the future OIDC credentials that Argo CD will later use when Authentik is deployed:
data:
  - secretKey: admin.password
    remoteRef:
      key: "{{ akv_argocd_admin_password_key }}"
  - secretKey: dex.authentik.clientId
    remoteRef:
      key: "{{ akv_authentik_client_id_key }}"
  - secretKey: dex.authentik.clientSecret
    remoteRef:
      key: "{{ akv_authentik_client_secret_key }}"
Although Authentik was not available yet, this meant that the Argo CD deployment was already prepared for a future migration to OIDC-based authentication.
Once synchronized, External Secrets Operator generates the required Kubernetes Secrets automatically. Because the repository Secret is labeled as an Argo CD repository Secret, Argo CD immediately discovers it and registers the repository without requiring any manual configuration.
To verify that synchronization completed successfully:
kubectl -n argocd get externalsecretYou should also see the generated repository Secret:
kubectl -n argocd get secret gitops-repoAfter synchronization finishes, the repository should appear in the Argo CD UI:
Settings
└── Repositories
The repository should be displayed with a successful connection status, confirming that Argo CD can authenticate and pull manifests directly from Git.
At this point Argo CD is fully connected to the GitOps repository and ready to manage the entire platform. The next step is designing the repository structure that will allow infrastructure, platform services, monitoring stacks, and application workloads to be deployed independently while remaining part of a single GitOps workflow.
We can log in with the bootstrap/break-glass account to the ArgoCD now.


Designing the GitOps Repository Structure
With the repository connected, Argo CD can finally start deploying workloads. Before creating any applications, however, I wanted to establish a repository structure that would remain maintainable as the platform grows.
One common mistake in GitOps repositories is placing everything into a single directory and allowing Argo CD to deploy every manifest it finds. While this works initially, it quickly becomes difficult to manage once infrastructure services, monitoring stacks, platform components, and application workloads start accumulating.
To avoid that problem, I separated the repository into several logical layers:
0-argocd/
├── 0-bootstrap/
├── 10-projects/
└── 20-applications/
10-infra/
15-platform/
20-monitoring/
30-apps/
Each directory represents a different responsibility within the platform:
- 0-argocd -Argo CD configuration and bootstrap
- 10-infra -Infrastructure services required by the cluster
- 15-platform -Shared platform services
- 20-monitoring -Monitoring and observability stack
- 30-apps -Business and application workloads
At the top level, I use the Apps-of-Apps pattern. Rather than creating every Argo CD Application manually, a small bootstrap application creates a set of root applications that are responsible for discovering workloads in each layer.
The deployment flow looks like this:
gitops-bootstrap
        │
        ▼
argocd-projects
        │
        ▼
argocd-root-applications
        │
        ├──────────┬────────────┬─────────┐
        ▼          ▼            ▼         ▼
      Infra     Platform    Monitoring   Apps
The first root application deploys all Argo CD Projects:
metadata:
  name: argocd-projects
spec:
  source:
    path: 0-argocd/10-projects
The second root application deploys all workload categories:
metadata:
  name: argocd-root-applications
spec:
  source:
    path: 0-argocd/20-applications
Each root application then recursively discovers individual application.yaml files within a dedicated directory.
For example, the infrastructure layer is configured as follows:
apiVersion: argoproj.io/v1alpha1
kind: Application
metadata:
  name: infra
  namespace: argocd
  annotations:
    argocd.argoproj.io/sync-wave: "0"
spec:
  project: infra
  source:
    repoURL: https://gitlab.<your-domain>/cloud-team/lab-infra/gitops.git
    targetRevision: main
    path: 10-infra
    directory:
      recurse: true
      include: "*/application.yaml"
  destination:
    server: https://kubernetes.default.svc
    namespace: argocd
syncPolicy:
automated:
prune: true
selfHeal: trueThis means that any folder under 10-infra containing an application.yaml file automatically becomes part of the infrastructure layer managed by Argo CD.
As a result, onboarding a new service becomes extremely simple:
10-infra/
└── 150-new-service/
    ├── application.yaml
    ├── values.yaml
    └── config/
After committing the changes, Argo CD automatically discovers the new application and reconciles it without any additional manual configuration.
I also use dedicated Argo CD Projects to enforce separation between different workload categories:
infra
platform
monitoring
apps
This provides a clean security boundary between infrastructure administrators, platform operators, and application teams while still keeping everything managed through a single GitOps repository.
The final result is a repository structure that scales naturally. Infrastructure, platform services, monitoring stacks, and application workloads can evolve independently while still being deployed through a single GitOps workflow managed entirely by Argo CD.
The next step is defining deployment ordering so that infrastructure services are installed before platform workloads, monitoring components, and applications.
Controlling Deployment Order with Sync Waves
With the repository structure in place, the next challenge is deployment ordering.
Not all components of the platform can be deployed simultaneously. Certain services depend on others being available first. For example, certificates require cert-manager, ingress resources require Traefik, and workload namespaces often depend on infrastructure components already existing.
To solve this problem, I use Argo CD Sync Waves.
A Sync Wave is simply an annotation that tells Argo CD in which order resources should be synchronized. Applications with lower values are deployed first, while higher values are deployed later.
metadata:
  annotations:
    argocd.argoproj.io/sync-wave: "20"
This allows the entire platform to be deployed automatically while still respecting dependencies between components.
The deployment flow in my environment looks as follows:
-500  Argo CD Projects
-300  Root Applications
  20  cert-manager
  25  ClusterIssuer
  30  MetalLB
  35  MetalLB Configuration
  40  Traefik
  45  ExternalDNS Secrets
  50  ExternalDNS
  55  Argo CD Ingress
  60  Rancher
  65  Longhorn
  70  Velero
  75  Cloudflared
 500+ Platform Services
1000+ Monitoring
1500+ Applications
The infrastructure layer is deployed first because nearly every other workload depends on it.
For example, cert-manager is installed before the Let’s Encrypt ClusterIssuer:
cert-manager
    ↓
ClusterIssuer
    ↓
Certificates
The same approach is used throughout the platform. Longhorn and Velero are deployed only after networking and ingress components are available, while platform services are deployed only after the infrastructure layer becomes healthy.
This ordering also simplifies troubleshooting. If a workload fails to deploy, Argo CD clearly shows the synchronization stage where the deployment stopped, making dependency-related issues significantly easier to identify.
An additional benefit of Sync Waves is that new services can be inserted into the deployment chain without modifying existing applications. For example, when I introduced Authentik, I simply assigned higher Sync Waves than the infrastructure components:
505  Homepage
505  Authentik PostgreSQL
510  Authentik
510  WikiJS PostgreSQL
515  WikiJS
540  GitLab Runner
This ensures that all required infrastructure components are already running before platform services begin deployment.
As a result, a fresh Argo CD bootstrap can deploy the entire platform from an empty cluster without any manual intervention. Argo CD automatically processes applications in the correct order, turning the Git repository into the single source of truth not only for configuration, but also for deployment orchestration.
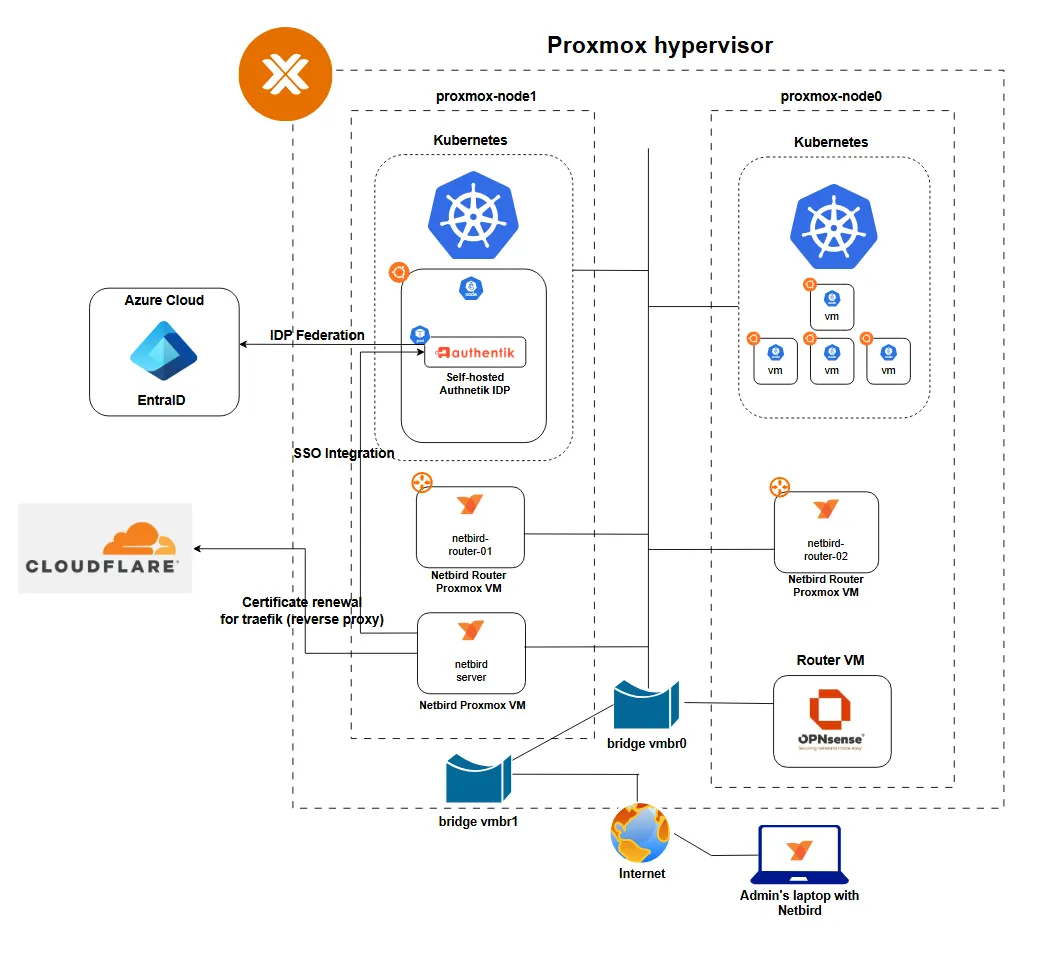
The target outcome of our deployment is an architecture like this.

Infrastructure and Platform Workloads
With the GitOps repository structure, the Secrets added to the the Azure Key Vault (I’ve omitted this part, you can inspect the ExternalSecrets objects here to know which secrets to create) and deployment ordering in place, the platform can start deploying actual workloads.
I divided the environment into four logical layers:
10-infra      → Cluster infrastructure
15-platform   → Shared platform services
20-monitoring → Observability stack
30-apps       → Application workloads
The infrastructure layer contains all components required to operate the cluster itself.
cert-manager
The first infrastructure component is cert-manager. It is responsible for automatically issuing and renewing TLS certificates across the platform.
Certificates are issued through Let’s Encrypt using the DNS-01 challenge. A Cloudflare API token is stored in Azure Key Vault, synchronized into the cluster using External Secrets Operator, and then consumed by a ClusterIssuer used by cert-manager.
This allows certificates to be provisioned and renewed automatically without any manual intervention.
MetalLB
Since this platform runs on-premises rather than in a public cloud, there is no cloud provider load balancer available.
MetalLB solves this problem by providing LoadBalancer functionality inside the Kubernetes cluster. It is responsible for allocating IP addresses from predefined address pools and exposing services to the network.
Without MetalLB, services using:
type: LoadBalancerwould remain in a pending state because Kubernetes would have no mechanism for assigning external IP addresses.
The deployment is split into two parts:
MetalLB Core
        │
        ▼
MetalLB Configuration
This ensures that the controller is available before address pools and advertisements are applied.
Traefik
Traefik acts as the platform’s ingress controller.
It is responsible for:
- Terminating TLS connections
- Routing traffic to workloads
- Loading TLS certificates generated by cert-manager
- Processing IngressRoute resources
- Providing a single entry point for all HTTP and HTTPS traffic
Most platform services are exposed through Traefik.
A typical traffic flow looks like:
Internet
    │
    ▼
 Traefik
    │
    ▼
IngressRoute
    │
    ▼
 Service
    │
    ▼
   Pod
The below diagram shows how the above components cooperate to provision the IPs, routing and certificates with the help of Cloudflare (where I manage my domain).

ExternalDNS
Managing DNS records manually quickly becomes difficult as new services are deployed. ExternalDNS solves this problem by watching Kubernetes resources and automatically creating DNS records in Cloudflare.
Get Aleksander Chotecki’s stories in your inbox
Join Medium for free to get updates from this writer.
The Cloudflare token is retrieved from Azure Key Vault through External Secrets Operator, meaning no DNS credentials are hardcoded inside Git repositories.
A typical flow looks as follows:
IngressRoute
        │
        ▼
ExternalDNS
        │
        ▼
Cloudflare DNS Record
As soon as a new application exposes a hostname, ExternalDNS automatically creates the corresponding DNS entry.
Cloudflared
The platform also integrates with Cloudflare using Cloudflare Tunnel.
Instead of exposing services directly to the internet through port forwarding, Cloudflared creates an outbound tunnel from the Kubernetes cluster to Cloudflare.
The resulting architecture looks like this:
Internet
    │
    ▼
Cloudflare
    │
    ▼
Cloudflare Tunnel
    │
    ▼
Cloudflared
    │
    ▼
 Traefik
    │
    ▼
Application
This approach provides several advantages:
- No inbound ports need to be opened
- Public services can remain behind Cloudflare
- Additional Cloudflare security controls can be applied
- Origin infrastructure remains hidden from the internet
To improve availability, Cloudflared runs multiple replicas.
Rancher
Rancher provides a centralized management interface for the Kubernetes environment.
While most platform operations are performed through GitOps and Argo CD, Rancher remains useful for:
- Cluster administration
- Node management
- Workload inspection
- Troubleshooting
- User access management (kubeconfigs)
The initial Rancher bootstrap password is also synchronized from Azure Key Vault using External Secrets Operator, ensuring that administrative credentials never need to be stored in Git.
Longhorn
Longhorn provides distributed block storage for the platform.
Persistent Volumes are automatically replicated across cluster nodes, allowing workloads to survive individual node failures.
Longhorn is used by multiple platform components that require persistent storage.

The deployment also creates recurring backup jobs which automatically export Longhorn backups to Azure Blob Storage according to a defined retention policy.
Remember to disable this setting in Longhorn, so that Longhorn replicas can be distributed across different zones and failure domains. In my case, the Kubernetes nodes that are hosted on a different bare metal Proxmox node have different zone labels (this configuration is part of Ansible scripts).

Velero
Velero complements Longhorn by providing Kubernetes-level backup and disaster recovery capabilities.
While Longhorn focuses on persistent volume data, Velero captures cluster resources such as:
- Deployments
- Services
- ConfigMaps
- Secrets
- Namespaces
- Persistent Volume metadata
Backups are automatically scheduled and stored in Azure Blob Storage (if you configure proper Azure Key Vault credentials for the Blob Storage).
This provides an additional recovery layer beyond volume-level backups and allows complete workload restoration if necessary.
With the infrastructure layer deployed, the cluster now has everything required to host higher-level services:
Certificates
Networking
Ingress
Load Balancing
DNS Automation
Cloudflare Integration
Persistent Storage
Backups
Cluster Management
The next layer builds on top of this foundation and introduces shared platform services such as Homepage, Authentik, Wiki.js, and GitLab Runner.
Deploying Platform Services
With the infrastructure layer fully operational, the cluster now provides everything required to host higher-level workloads.
At this point, the platform has:
- TLS certificate automation
- DNS automation
- Ingress routing
- Cloudflare integration
- Persistent storage
- Backup and recovery
- Cluster management
The next layer consists of platform services. These workloads are not strictly required for Kubernetes itself to function, but they provide capabilities that make the platform usable by administrators and application teams.
In my environment, the platform layer currently contains:
Homepage
Authentik
Wiki.js
GitLab Runner
Unlike the infrastructure layer, these workloads depend on services that were deployed previously. For example, they consume TLS certificates issued by cert-manager, use storage provisioned by Longhorn, and expose endpoints through Traefik and Cloudflare.
Homepage
Homepage acts as the landing page for the platform.
As the number of services increased, keeping track of URLs, dashboards, and administrative interfaces becomes increasingly difficult. Homepage provides a centralized dashboard where platform services can be organized and accessed from a single location.
The service itself is deployed through Argo CD as a standard Helm chart and follows the same GitOps workflow as every other workload in the environment.

Authentik
One of the primary goals of this platform is centralized identity and access management.
While Argo CD was already prepared for OIDC integration in the previous article, the identity provider itself had not yet been deployed.
To solve this problem, I chose Authentik.

Up to this point, most services could be accessed using local accounts, bootstrap credentials, or service-specific authentication mechanisms. While this approach works for a small number of services, it quickly becomes difficult to manage as the platform grows.
I wanted a single identity provider that could handle authentication for platform services such as Argo CD, Rancher, Grafana, NetBird, and future applications deployed to the cluster. After evaluating several options, I chose Authentik.
The main reasons were:
- Fully self-hosted
- Native OIDC and SAML support
- Flexible group-based authorization
- Straightforward Kubernetes deployment
- Excellent integration with cloud-native platforms
Since Argo CD had already been prepared for future OIDC integration in the previous section, introducing Authentik later would not require significant modifications to the GitOps structure.
Authentik PostgreSQL
Authentik requires a PostgreSQL database backend.
Rather than deploying the database manually, I created a dedicated Argo CD application responsible for PostgreSQL deployment.
The PostgreSQL deployment uses Longhorn-backed persistent storage, ensuring that database data survives pod restarts, node maintenance events, and cluster upgrades.
As with every other platform component, the deployment is managed entirely through Argo CD and GitOps.
Authentik Secrets from Azure Key Vault
One of the advantages of introducing Azure Key Vault and External Secrets Operator earlier in the series is that new workloads automatically inherit the same secret management model.
Authentik requires a secret key used internally for cryptographic operations. Rather than storing this value in Git or directly in Kubernetes, it is maintained in Azure Key Vault and synchronized through External Secrets Operator.
apiVersion: external-secrets.io/v1
kind: ExternalSecret
metadata:
  name: authentik-secret
  namespace: authentik
spec:
  refreshInterval: 10m
  secretStoreRef:
    kind: ClusterSecretStore
    name: azure-kv
  target:
    name: authentik-secret
    creationPolicy: Owner
  data:
    - secretKey: AUTHENTIK_SECRET_KEY
      remoteRef:
        key: authentik-secret-key
Authentik Application
Like every other platform service, Authentik is deployed through its own Argo CD Application.
The application definition follows the same structure used throughout the repository:
15-platform/
└── authentik/
    ├── application.yaml
    ├── values.yaml
    └── config/
The Application references the Authentik Helm chart, applies platform-specific configuration, and enables automated synchronization.
Because it lives in the 15-platform layer, it is automatically discovered by the root Platform application without requiring any additional Argo CD configuration.
Adding a new platform service follows exactly the same workflow:
Create a folder
Commit changes
Push to Git
Argo CD deploys automatically
Authentik IngressRoute
Once Authentik is deployed, it needs to be exposed externally.
Like the rest of the platform, incoming traffic is routed through Traefik, but in this case we use cloudflared to expose it via the Cloudflare Tunnel.
The resulting request path looks like this:
Internet
     │
     ▼
Cloudflare
     │
     ▼
Cloudflare Tunnel
     │
     ▼
Cloudflared
     │
     ▼
Traefik
     │
     ▼
Authentik
The manifest should look like this:
# For cloudflare DNS record should not be created with extenal-dns, so here we remove external dns annotation
apiVersion: traefik.io/v1alpha1
kind: IngressRoute
metadata:
  name: authentik-cloudflared
  namespace: authentik
spec:
  entryPoints:
    - cloudflared
  routes:
    - match: Host(`auth.<your_domain>`)
      kind: Rule
      services:
        - name: authentik-server
          port: 80
  #
  # tls:
  #   secretName: authentik-tls
When using cloudflared the TLS will be provided by the Cloudflare, we don’t need to configure the cert-manager Certificate object for it. The entryPoint configuration corresponds to this Traefik configuration:

In the Cloudflare Tunnel options you need to point your domain you want to publish the Authentik instance with to the Traefik service like this:

This approach avoids exposing Kubernetes nodes directly to the internet while still allowing secure access to the Authentik portal.
The only public endpoint visible to users is the Authentik hostname:
https://auth.<your_domain>.comHowever, after opening the link you should be prompted with registration of your first account. This is not safe, as you expose the installation to the Internet. What I did instead, I’ve disabled the published route in Cloudflare and I’ve installed it by exposing it to the VPN network and getting the certificate for a different domain (authentik.<your_domain>.com).
apiVersion: cert-manager.io/v1
kind: Certificate
metadata:
  name: authentik-tls
  namespace: authentik
spec:
  secretName: authentik-tls
  issuerRef:
    name: letsencrypt-prod
    kind: ClusterIssuer
  dnsNames:
    # auth.<your_domain> has cert managed by cloudflare tunnel
   # - auth.<your_domain>
   # this domain is only for internal VPN-based access. Using it for SSO will fail.
   - authentik.<your_domain>
---
apiVersion: traefik.io/v1alpha1
kind: IngressRoute
metadata:
  name: authentik
  namespace: authentik
  annotations:
    external-dns.alpha.kubernetes.io/target: ingress.<your_domain>
spec:
  entryPoints:
    - websecure
  routes:
    - match: Host(`authentik.<your_domain>`)
      kind: Rule
      services:
        - name: authentik-server
          port: 80
  tls:
    secretName: authentik-tls
After creating the initial account via the VPN network the instance should be operational and can be exposed via the cloudflared. For additional security layer you can configure Cloudflare WAF, but you should allowlist traffic originating from the cluster egress IP address as the ‘managed-challenges’ can break the OIDC integrations we will make in the future articles.

Future Integrations
At this stage, Authentik is deployed and operational, but it is not yet serving as the central identity provider for the platform.
The goal is to gradually migrate services toward centralized authentication using OIDC.
Several services have already been prepared for that transition. For example, Argo CD is configured to retrieve future Authentik OIDC client credentials from Azure Key Vault through External Secrets Operator. This allows OIDC integration to be enabled later without changing the overall GitOps architecture.
In future articles, I will integrate Authentik with:
- Argo CD
- Rancher
- Grafana
- NetBird
The end goal is to have a single authentication platform providing centralized identity management, group-based authorization, and single sign-on across the entire Kubernetes environment.
This integration will be covered in a future article.