Ask My dbt Project: A dbt Cloud Connector for Cognee
Turning dbt Cloud’s manifest and run history into memory an AI agent can actually query.
A dbt project is fine when it’s a dozen models. Past that, the hard questions stop being about SQL. They turn into: what actually depends on orders, did last night's Build job pass, and which test is failing right now. The answers live in three different places — the manifest, the run history, and whatever's in someone's head — and none of them are a text box you can ask a question in.
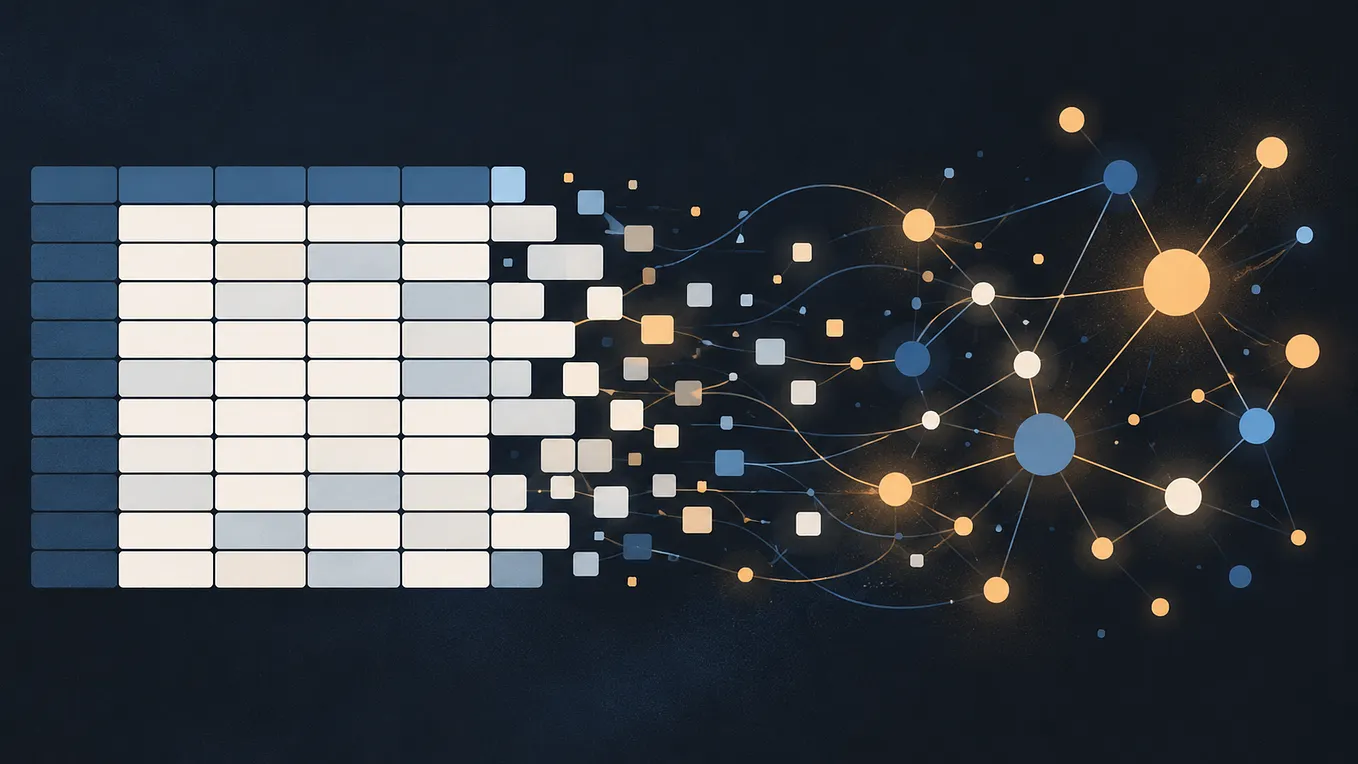
That’s the gap I built a connector for: pull dbt Cloud’s model documentation, lineage, and job run outcomes into Cognee, so you can ask about your project in plain language instead of grepping a manifest file.
Cognee and what a connector is
Cognee is a memory layer for AI agents. You give it data, it extracts entities and relationships into a graph plus a vector index, and you query it with natural language instead of writing SQL or re-reading docs every time. A connector is the piece that turns some external system — dbt Cloud, Notion, Google Drive, Slack — into documents Cognee can ingest, using dlt under the hood.
I built this one during Mergetober, WeMakeDevs’ hackathon paired with Cognee to grow its connector ecosystem.
What the connector does
dbt_cloud_source() returns a dlt source. You point it at an account and a selection — an environment, a project, or specific jobs — and it does this on every sync:
resolve jobs (environment_ids / project_ids / job_ids)
  -> for each job: list runs (state=active, newest first)
  -> parse each environment's latest successful run's manifest
  -> manifest -> one document per model/source/seed/snapshot/exposure/metric
  -> run_results.json -> one document per finished run
  -> hand rows to dlt; merge write_disposition tombstones what's gone
Definitions and run outcomes go in as normal documents, so they flow through Cognee’s full entity-extraction pipeline — not the deterministic row-by-row path some other connectors use. That matters because lineage and failure messages are prose Cognee needs to reason over, not structured rows to look up.
Setting it up
This is the real call, copied from examples/example.py:
from cognee_community_connector_dbt_cloud import dbt_cloud_sourcesource = dbt_cloud_source(
account_id=account_id,
environment_ids=environment_ids, # or project_ids=[...] / job_ids=[...]
)await cognee.remember(
source,
dataset_name="dbt_cloud",
primary_key="id",
write_disposition="merge",
max_rows_per_table=0,
)
write_disposition="merge" and max_rows_per_table=0 aren't optional extras — cognee.remember() defaults to "replace" if you don't pass them, and the default row cap is 50, which a real project blows through immediately. You need a personal access token or service account token with read-only access to Jobs, Runs, and Artifacts, and the Administrative API itself needs a dbt plan that includes it — the free Developer plan doesn't.
Why I parse the manifest instead of walking the API
The manifest already contains the full lineage graph — parent_map and child_map for every node, plus descriptions, columns, tags, and attached tests. Walking the API node by node would mean dozens of calls to reconstruct something manifest.json hands you in one file. So each environment's latest successful run's manifest is the source of truth for definitions, fetched once per sync.
Here’s roughly what a rendered definition document looks like, from the test suite:
Resource type: model
Materialized: table
Tests:
- not_null on column idUpstream: customers (model.jaffle_shop.customers)
Downstream: orders (model.jaffle_shop.orders)
One document per model, source, seed, snapshot, exposure, or metric. Lineage and tests are written as text instead of kept as IDs, so Cognee’s graph extraction can connect a model to what feeds it and what it feeds, across documents, without a separate join step.
Run outcomes are a second document family — one per finished run, holding status, git branch and sha, and the failing or erroring nodes pulled from run_results.json. These aren't kept forever: each job only keeps its newest max_runs_per_job finished runs (50 by default) as a sliding window. Older runs age out and get forgotten the same way deleted ones do.
Why incremental sync doesn’t trust the obvious things
The easy version of incremental sync is “compare timestamps, sync what’s newer.” dbt Cloud’s run timestamps come back in slightly different ISO formats — sometimes a Z suffix, sometimes an explicit offset, sometimes missing fractional seconds — which sort incorrectly if you compare them as strings even though they're fine as actual datetimes. So every comparison goes through real datetime parsing, never string comparison.
The run listing is also supposed to come back newest-first, but the connector doesn’t take that on faith either — it tracks whether the observed order actually holds and falls back to scanning further rather than assuming an early stop is safe if it doesn’t.
On top of that, a sha256 hash over the resolved scope (account, project/environment/job ids, resource types, and the include_* flags) decides whether a sync is a full pass or incremental. Change any of that config and the next sync re-evaluates everything from scratch, rather than silently applying old assumptions to a different scope.
Forgetting things safely
A model deleted from the project, a run that aged out of the window, a job that got archived — all of it needs to disappear from the graph, not just stop getting updated. The connector does this by emitting a {"id": ..., "_deleted": True} tombstone row; dlt's merge disposition physically removes the matching row, and Cognee's orphan cleanup takes it from there. The connector itself never deletes anything directly.
Get Jeswanimohit’s stories in your inbox
Join Medium for free to get updates from this writer.
The part that took more thought is not over-triggering this. A flaky API response with zero jobs isn’t the same as every job being deleted, and the connector treats them differently: an environment with no successful runs keeps its last known definitions instead of wiping them, and vanished-job detection on a full pass is skipped entirely if the current job resolution itself comes back empty. An honest false positive here would mean losing a whole project’s memory because of one bad API response.
What happened when I ran it for real
I tested this against a real dbt Cloud Starter trial (14 days, no credit card), connected to a free Neon Postgres database as the warehouse, running dbt’s own default scaffolded project — my_first_dbt_model and my_second_dbt_model, one depending on the other, built by a real "Build" job.

First sync, full pass, real API calls:
dbt Cloud: resolved 2 job(s): 70506183142809:Build, 70506183142810:Build
dbt Cloud: full sync yielded 7 document(s) across 2 job(s).
Cognee cognified those documents — Gemini as the LLM, local fastembed for embeddings, no OpenAI key needed — and I asked it one real question:
Query: “Summarize the models in this project and whether their latest runs passed.”
Answer: “The project contains two models:
my_first_dbt_model(a starter table model) andmy_second_dbt_model(a downstream table model that depends onmy_first_dbt_model). Their latest run (Run 70506183987551) passed successfully with a status of Success."
Both model names correct, the dependency direction correct, the real run ID, the real status — all pulled from the live account, not a fixture.
Then I ran the exact same script again, no changes made upstream:
dbt Cloud: resolved 2 job(s): 70506183142809:Build, 70506183142810:Build
dbt Cloud: incremental sync yielded 0 document(s) across 2 job(s).
Nothing re-fetched, nothing re-ingested. The incremental cursor and the “skip if the environment’s latest successful run is unchanged” check both held up against a live account, not just the fake-session test suite.
What I’d ask it
The one question above was a sanity check. The kind of thing this is actually for is more like:
- Which models would break if I dropped the
customerstable? - What were the last few failures on the nightly Build job, and which test caused them?
- Which models still have no description or no owner tagged?
None of these are things I’ve measured — they’re the shape of question this connector exists to answer once a project has more than two models in it.
What it doesn’t do
Raw and compiled SQL are off by default — include_sql=True turns it on, but SQL can be large and occasionally holds things you don't want duplicated into a graph. CI and merge-triggered jobs are excluded by default too, since they run against ephemeral branches rather than your project's stable definition. Macros, analyses, docs blocks, and selectors are never ingested, and there's no Discovery API support or source-freshness data.
Artifacts are capped at max_artifact_mb (200MB by default) so a huge manifest can't blow up memory. And the Administrative API itself is plan-gated — Developer accounts don't get it, so you need Starter or above, or the 14-day trial, which auto-downgrades if you don't upgrade it.
Try it
The connector lives at packages/connector/dbt-cloud/ in cognee-community. Full details, including the live-test writeup, are in PR #360, which closes issue #4775. Cognee's docs are at docs.cognee.ai, and this was built for Mergetober, WeMakeDevs' hackathon with Cognee.
If you’ve got a dbt Cloud project past the “I remember what everything does” stage, it’s worth pointing this at it and seeing what comes back.
I used an AI assistant while building this connector and while drafting this post; I ran everything myself and edited the text.