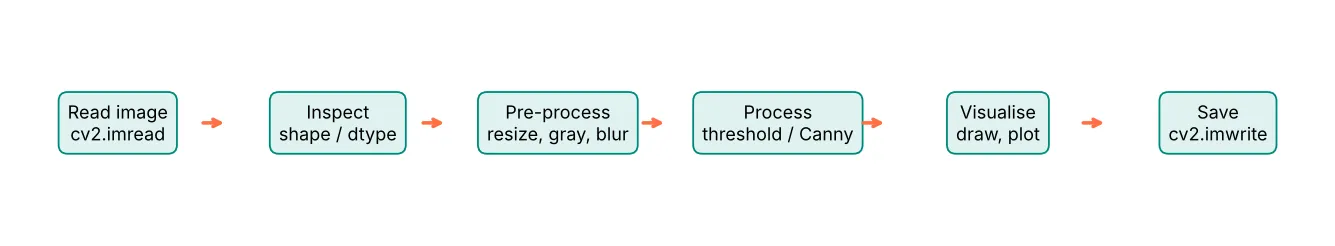
Part 4: How to Teach a Computer to “See” Objects

Mastering Digital Image Processing
Welcome back ppl…
If you’ve been consistent with the previous parts… You’ve blurred, sharpened, and turned selfies into art. Now the real game begins:
How do you make a computer look at a photo and say, “This is the cat. This is the background. These are the coins on the table.”
Chapter 1: The Dumbest Way That Surprisingly Works 90% of the Time
Thresholding is the simplest form of segmentation and is based on the assumption that objects and background have distinct intensity ranges. Global thresholding equation:
dst(x,y) = 255 if src(x,y) > T
0 otherwise
The entire game is choosing T.
Rule: If pixel > some value.. that’s foreground
Else = background
import cv2
import matplotlib.pyplot as plt

img = cv2.imread('coins.jpg', 0)
_, thresh = cv2.threshold(img, 127, 255, cv2.THRESH_BINARY)

plt.figure(figsize=(10,5))
plt.subplot(121), plt.imshow(img, cmap='gray'), plt.title('Original')
plt.subplot(122), plt.imshow(thresh, cmap='gray'), plt.title('Global Threshold = 127')
plt.show()
Works perfectly… when lighting is even.
Chapter 2: When Global Threshold Fails…
Take a photo with shadow on one side… half the coins disappear.
The fix is.. Adaptive Thresholding (let each region choose its own threshold)
adaptive = cv2.adaptiveThreshold(img, 255, cv2.ADAPTIVE_THRESH_GAUSSIAN_C,cv2.THRESH_BINARY, 11, 2)

plt.imshow(adaptive, cmap='gray')
plt.title('Adaptive Threshold – Shadow? What shadow?')
No more manual tuning. The algorithm looks at nearby pixels and decides locally.
Chapter 3: Otsu
Otsu’s method automatically finds the best threshold by minimizing variance between foreground and background.
Otsu treats threshold selection as an optimization problem.
It tries every possible T from 0 to 255 and computes:
- ω₀(T) = probability of class 0 (background)
- ω₁(T) = probability of class 1 (foreground)
- σ²₀(T) and σ²₁(T) = variance of each class
Then it minimizes the weighted within-class variance:
σ²_w(T) = ω₀(T)·σ²₀(T) + ω₁(T)·σ²₁(T)
Or equivalently maximizes between-class variance (same result, faster).
In plain words: Otsu finds the threshold that makes the two groups as tight as possible and as far apart as possible. That’s why it magically works on almost every clean image.
_, otsu = cv2.threshold(img, 0, 255, cv2.THRESH_BINARY + cv2.THRESH_OTSU)
print("Otsu chose threshold:", _)   # usually around 100-150 for coins
One line. Zero guessing. Works on 90% of clean images.
Chapter 4: Morphology
Your threshold is perfect… except for tiny holes and noisy specks.
Morphology treats binary (or grayscale) images as sets.
- Erosion: A ⊖ B = { z | (B)z ⊆ A } → every pixel where the entire kernel fits inside the foreground stays foreground.
- Dilation: A ⊕ B = { z | (B̂)z ∩ A ≠ ∅ } → any pixel the kernel touches becomes foreground.
Opening = erosion then dilation… this removes small objects and thin connections without changing big shapes.
Closing = dilation then erosion… this fills small holes and connects nearby objects.
Get K’s stories in your inbox
Join Medium for free to get updates from this writer.
These four operations are literally the “clean-up crew” of every segmentation pipeline.
kernel = np.ones((5,5), np.uint8)

opening = cv2.morphologyEx(thresh, cv2.MORPH_OPEN, kernel, iterations=2)
closing = cv2.morphologyEx(opening, cv2.MORPH_CLOSE, kernel, iterations=3)

plt.subplot(131), plt.imshow(thresh, cmap='gray'), plt.title('Raw Threshold')
plt.subplot(132), plt.imshow(opening, cmap='gray'), plt.title('After Opening')
plt.subplot(133), plt.imshow(closing, cmap='gray'), plt.title('After Closing – Clean!')
Now your coins look like they were drawn by a perfectionist.
Chapter 5: Watershed
Classic watershed (Vincent & Soille, 1991) works on the gradient magnitude image. Think of the gradient image as a height map:
- Low gradient (smooth areas) are valleys
- High gradient (edges) are mountain ridges
Algorithm steps:
- Sort all pixels by increasing gray value (height)
- “Flood” from the lowest points (local minima)
- When two basins are about to merge, build a dam… that dam becomes the segmentation boundary
Coins touching? Cells overlapping under microscope? Same problem.
# Step-by-step watershed (the classic algorithm everyone uses)

# 1. Clean binary
binary = closing

# 2. Distance transform (how far each pixel is from background)
dist = cv2.distanceTransform(binary, cv2.DIST_L2, 5)
_, sure_fg = cv2.threshold(dist, 0.7*dist.max(), 255, 0)

# 3. Find sure background
sure_bg = cv2.dilate(binary, kernel, iterations=3)

# 4. Unknown region
unknown = cv2.subtract(sure_bg, sure_fg)

# 5. Label markers
_, markers = cv2.connectedComponents(sure_fg)
markers = markers + 1
markers[unknown==255] = 0

# 6. Finally watershed
img_color = cv2.imread('coins.jpg')
markers = cv2.watershed(img_color, markers)
img_color[markers == -1] = [255,0,0]  # boundaries in red

plt.imshow(cv2.cvtColor(img_color, cv2.COLOR_BGR2RGB))
plt.title('Watershed – Every coin perfectly separated')
Even touching coins are perfectly separated with red boundaries.
This exact code(as base ideation) is used in:
- Counting blood cells in medical labs
- Segmenting tumors in MRI scans
- Detecting defects on factory assembly lines
Mini Project: Build Your Own Coin Counter
# After watershed
contours, _ = cv2.findContours(binary, cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE)
print(f"I found {len(contours)} coins!")

# Draw count on image
output = cv2.imread('coins.jpg')
cv2.putText(output, f"Count: {len(contours)}", (50,100),
            cv2.FONT_HERSHEY_SIMPLEX, 3, (0,255,0), 8)
cv2.imwrite('counted_coins.jpg', output)
Run it on any coin photo and have your own instant counter.
Remember this…
- Global threshold is simple but fragile
- Adaptive + Otsu is basically set-it and forget-it
- Morphology cleans up the mess
- Watershed helps solve the “touching objects” problem forever
- Segmentation is the foundation of object detection, medical imaging, self-driving cars
Next post: We go from “where are the objects?” to “what ARE the objects?” We’ll extract features (SIFT, HOG) and build actual object detectors the old-school way… before deep learning took over.
See you in Part 5.
— Krrish