Build A Number Plate Recognition System From Scratch (YOLOv4, Tesseract, and Python)


Deep Learning is an interdisciplinary field that has been gaining huge amounts of traction in recent years and Computer Vision has taken center stage. An integral part of Computer Vision is object detection. Object detection aids in pose estimation, vehicle detection, surveillance, etc. The difference between object detection algorithms and classification algorithms is that in detection algorithms, we try to draw a bounding box around the object of interest to locate it within the image. Also, you might not necessarily draw just one bounding box in an object detection case, there could be many bounding boxes representing different objects of interest within the image and you would not know how many beforehand.
Recognizing Number Plate is a very important task for a camera surveillance-based security system. We can extract the Number plate from an image using some computer vision techniques and then we can use Optical Character Recognition to recognize the license number.
In this, you will build a Number Plate Recognition system using yolov4, Tesseract, and Python.
Introduction to YOLO
The YOLO framework (You Only Look Once) deals with object detection in a different way. It takes the entire image in a single instance and predicts the bounding box coordinates and class probabilities for these boxes. The advantage of using YOLO is its speed. It’s incredibly fast and can process 45 frames per second. YOLO also understands generalized object representation.
How Yolo works?
YOLO divides up the image into a grid of 13 by 13 cells: Each of these cells is responsible for predicting 5 bounding boxes. A bounding box describes the rectangle that encloses an object. YOLO also outputs a confidence score that tells us how certain it is that the predicted bounding box actually encloses some object.
YOLO uses a totally different approach. It applies a single neural network to the full image. This network divides the image into regions and predicts bounding boxes and probabilities for each region. These bounding boxes are weighted by the predicted probabilities.
Step 1: Take input an image
Step 2: Create Grid on Images
Step 3: Predict Bounding Box
How to use it?
Clone the Repository in your system
# git clone https://github.com/visionify/license-plate-detection.git# cd license-plate-detection
Create virtual environment and install required packages
With virtualenv and pip:
# TensorFlow CPU
pip install -r requirements.txt
# TensorFlow GPU
pip install -r requirements-gpu.txt
With conda:
# Tensorflow CPU
conda env create -f conda-cpu.yml
conda activate yolov4-cpu
# Tensorflow GPU
conda env create -f conda-gpu.yml
conda activate yolov4-gpu
For this guide, we already trained the model on the Licence plate to identify in images.
You can download the pre-train model here: https://drive.google.com/file/d/1ivdpD0vDOiZHi3oot02-v59eqICnI8pZ/view?usp=sharing
Copy and paste your license_plate.weights file into the ‘data’ folder.
# License plate yolov4
python save_model.py — weights ./data/license_plate.weights — output ./checkpoints/license_plate-416 — input_size 416 — model yolov4
# Run license plate yolov4 tensorflow model
python detect.py — weights ./checkpoints/license_plate-416 — size 416 — model yolov4 — images ./data/images/car.jpg
Get Suresh Thodety’s stories in your inbox
Join Medium for free to get updates from this writer.
Until here, we had created a script that processes an image and identify number plate and draws boundary over number plate.
Extract Text from Image
Now moving forward, to read text from the number plate we need to perform OCR on the image. We will use Tesseract OCR to extract text from images.
In order to run tesseract OCR, you must first download the binary files and set them up on your local machine. Please do so before proceeding or commands will not run as expected!
Official Tesseract OCR Github Repo: tesseract-ocr/tessdoc
For Windows, I recommend: Windows Install
Running License Plate Recognition
The license plate recognition works wonders on images. All you need to do is add the — plate flag on top of the command to run the custom YOLOv4 model.
Running License Plate Recognition on Images
# Run License Plate Recognition
python detect.py — weights ./checkpoints/custom-416 — size 416 — model yolov4 — images ./data/images/car2.jpg — plate
Running License Plate Recognition on Videos
python detect_video.py — weights ./checkpoints/custom-416 — size 416 — model yolov4 — video ./data/video/license_plate.mp4 — output ./detections/recognition.avi — plate
Under the Hood
Let’s understand, what steps we are performing to extract text from the image
When we give the above image to the model, it will identify the number plate inside images and draw a boundary box around it with confidence.
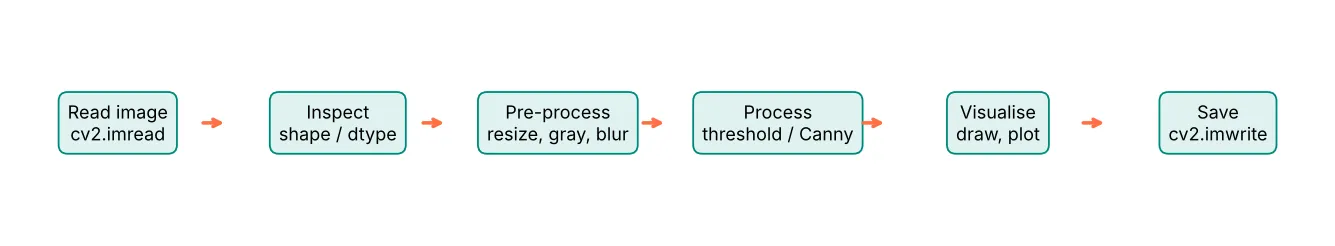
The first step of the process is taking the bounding box coordinates from YOLOv4 and simply taking the sub-image region within the bounds of the box. Since this image is super small the majority of the time we use cv2.resize() to blow the image up 3x its original size.
Then we convert the image to grayscale and apply a small Gaussian blur to smooth it out.
Following this, the image is thresholded to white text with a black background and has Otsu’s method also applied. This white text on black background helps to find the contours of the image.
The image is then dilated using OpenCV in order to make contours more visible and be picked up in future steps.
Next, we use OpenCV to find all the rectangular-shaped contours on the image and sort them left to right.
As you can see this causes many contours to be found other than just the contours of each character within the license plate number. In order to filter out the unwanted regions, we apply a couple of parameters to be met in order to accept a contour. These parameters are just height and width ratios (i.e. the height of the region must be at least 1/6th of the total height of the image). A couple of other parameters on the area of region etc are also placed. Check out the code to see exact details. This filtering leaves us with.
The individual characters of the license plate number are now the only regions of interest left. We segment each sub-image and apply a bitwise_not mask to flip the image to black text on a white background which Tesseract is more accurate with. The final step is applying a small median blur on the image and then it is passed to Tesseract to get the letter or number from it. Example of how letters look like when going to tesseract.
Each letter or number is then just appended together into a string and at the end, you get the full license plate that is recognized! BOOM!
In manufacturing facilities you need to check the product quality and its other attributes like labels, count, foreign objects,anamoly detection. But manual checking is not faster than machines. Machine vision systems can help you to solve those problems. Visionify is offering custom Computer Vision Solutions that could help you towards your goal. Call us to get a demo, we are ready to solve your manufacturing issues.