Member-only story
YoloV1 (You only look once)

Problem Statement: Efficiently detect and classify objects in images while balancing speed and accuracy.
Purpose: YOLOv1 performs real-time object detection, predicting bounding boxes and class probabilities directly from an input image in a single pass.
what kind of model is YOLO?
YOLOv1 is a single-stage object detection model.
let’s define what is single stage and multistage object detection model
Single-stage detection: Detects objects in one pass by directly predicting bounding boxes and class probabilities (e.g., YOLO, SSD). Faster but slightly less accurate.
Multi-stage detection: Performs detection in multiple steps, like generating region proposals first, then refining and classifying them (e.g., Faster R-CNN). More accurate but slower.
let’s discuss how yolov1 works:
Input Processing:
- The input image is resized to a fixed dimension (e.g., 448×448 for YOLOv1).
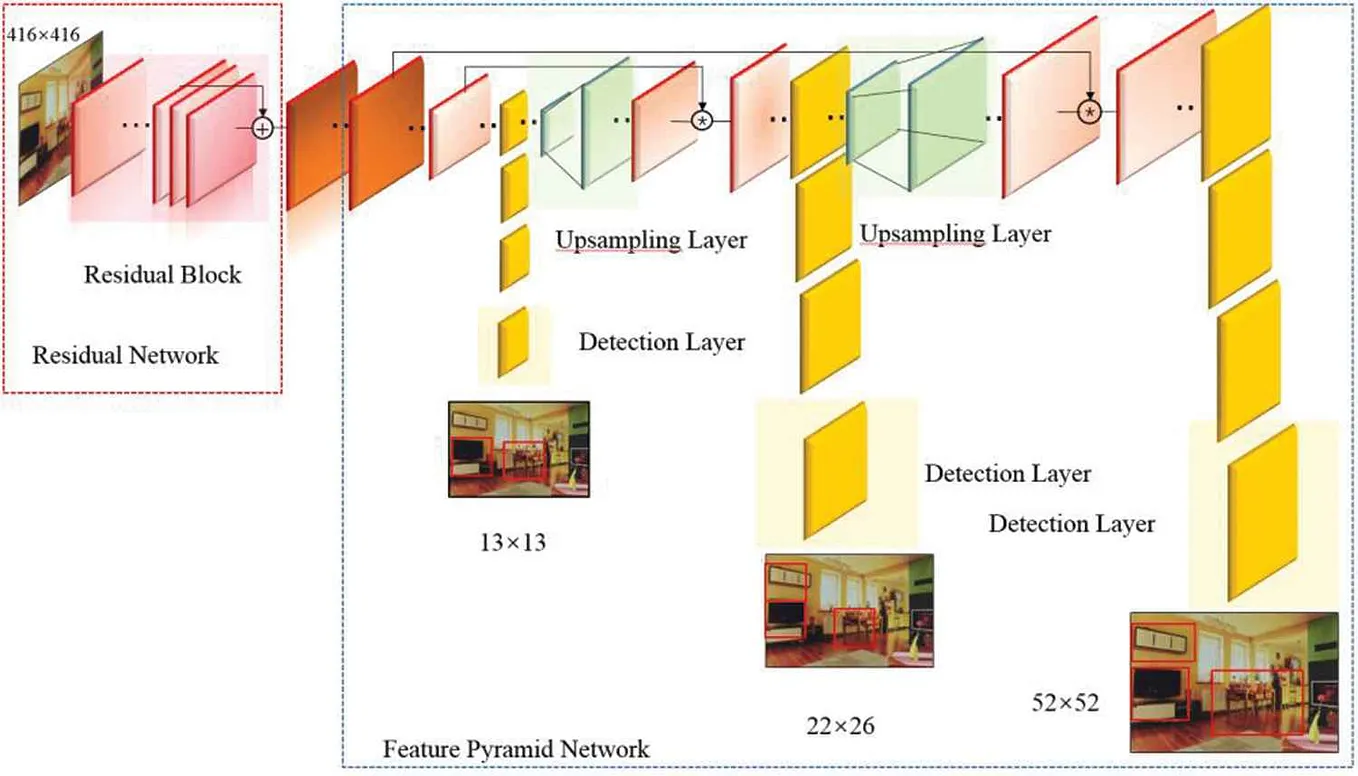
- The resized image is passed through a Convolutional Neural Network (CNN), specifically DarkNet in YOLOv1, to extract feature maps.