Guoliang(Gavin) Zhu·Oct 27How verl’s single controller worksRecently while chatting with claude, I came across verl and its single controller way of translating training.
Compass Investment·Oct 18Billionaire Ray Dalio warns that the surge in borrowing in the AI sector will collide with a flood…The AI-driven borrowing boom will soon be met with a significant increase in U.S. public debt, which threatens to drive up the cost of…
Yen-hua Chen·Sep 30Recovery Is Not ProgressA Ray Placement Group Case Study on Partial Recovery, Queue Starvation, and Scheduler LivenessA response icon1A response icon1
Shivank Chaudhary·Aug 12Serving a Multi-Node LLM on AMD MI300A over HPE Slingshot and Kubernetes [learning resource]Most “deploy an LLM” tutorials assume one box with a handful of NVIDIA GPUs, a CUDA image, and a single docker run. The moment your model…
InTowards AIbyGabriel Preda·Jul 31From Single-GPU PyTorch to Distributed Training with Ray: Three Experiments on Kaggle’s Dual T4…One of the most attractive promises of distributed deep learning is simple: add more GPUs and your model trains faster. In practice…A response icon1A response icon1
InzenigmabyCenkay Yaman·Jul 28Observability for LLMs on Ray Cluster: A Centralized Grafana Dashboard HubWhy default Ray dashboards aren’t enough for LLM serving, and how to track TTFT, throughput, KV cache usage, and replica metrics in one…
InSnowflake Builders Blog: Data Engineers, App Developers, AI, & Data SciencebyGarrett Frere·Jul 17Ray Distributed XGBoost on GPUGarrett Frere
Archana Suresh Patil·Jul 15Building a Distributed Hyperparameter Optimization Platform with Ray, Optuna, and MLflowHow I built a local-first ML platform that tunes models in parallel, survives worker crashes, and refuses to promote a model unless it’s…
Duy Nguyen·May 20MiniGPT with JAX and 3D Parallelism — ContinuedPart 2: Multinode training with Jax and Ray
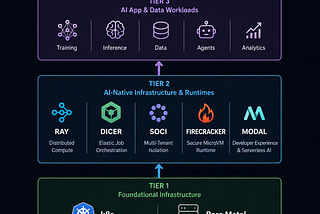
Eric Sun·Apr 27K8s Is Not Enough for The Coming Fracture of AI & Data InfrastructureThe orchestration layer that runs half the internet is quietly becoming the wrong abstraction for the workloads that matter most.