AI Is Not Creating a Writing Crisis in Science. It Is Creating an Evaluation Crisis.

The arXiv controversy reveals a deeper problem: when scientific production becomes nearly unlimited, how do we preserve the ability to distinguish knowledge from plausible-looking output?
Something important is happening in scientific publishing, and the problem may be considerably deeper than “AI slop.”
On October 1, 2026, arXiv, one of the world’s major open scientific repositories, announced an updated rate-limit policy covering submitters and categories. The organization described the measure as a temporary response while it develops better practices and improves its moderation tools and procedures.
The numbers explain the concern.
arXiv reported receiving 9,869 submissions in September 2016, 20,569 in September 2024, and 40,363 in September 2026. The September 2026 submissions generated almost 9,000 support tickets. It also reported that submissions to its cs.AI category increased by more than sixfold over the preceding two years.
arXiv explicitly identifies advanced AI tools as one factor contributing to this increase. Its moderators report more narrow “thin papers,” fragmented “salami papers,” and dense AI-written manuscripts that fail to satisfy the repository’s standards.
At first glance, this appears to be a publishing problem.
I believe it reveals something much more fundamental.
Science may be entering an evaluation crisis.
The Cost of Generation Is Collapsing
For most of scientific history, producing a manuscript required substantial effort.
A researcher had to formulate an argument, review previous work, organize evidence, construct the manuscript, revise it and prepare it for publication.
That effort created a natural constraint on volume.
Generative AI changes that constraint.
AI can dramatically accelerate drafting, restructuring, editing, literature organization and other parts of scientific communication. arXiv itself acknowledges this transformation, saying advanced AI tools are making aspects of research faster and easier.
That is not necessarily bad.
Used responsibly, AI could become one of the most powerful tools scientists have ever possessed.
But something asymmetrical is happening:
The cost of generating scientific-looking material is falling much faster than the cost of evaluating it.
And that changes the structure of scientific communication.
Generation Scales. Judgment Does Not.
Consider the difference.
An AI system can generate another manuscript very quickly.
But somebody still has to determine:
- Are the claims logically coherent?
- Do the references actually support them?
- Is the methodology appropriate?
- Does the evidence support the conclusions?
- Is the work genuinely novel?
- Are alternative explanations considered?
- Can the reasoning be reconstructed?
- Can the claims ultimately be tested or falsified?
Those questions require evaluation.
And evaluation remains expensive.
It requires time, expertise, attention and judgment.
This is precisely where the arXiv problem becomes interesting.
The organization says that the core of its process for identifying and rejecting low-quality papers depends upon volunteer moderators, while a relatively small proportion of authors submitting large numbers of low-quality papers consumes a disproportionate amount of moderator time.
In other words, the scarce resource is no longer necessarily the ability to produce information.
The scarce resource is the ability to evaluate it.
The Wrong Question: “Did AI Write This?”
There is a temptation to frame the problem as human science versus AI-generated science.
That distinction may eventually become increasingly unhelpful.
The relevant question should not simply be:
Did a human or an AI write this paper?
It should be:
Can the reasoning behind the paper be examined?
That changes the discussion considerably.
A human-written paper can contain bad reasoning.
An AI-assisted paper can contain good reasoning.
A prestigious institution can produce an incorrect conclusion.
An independent researcher can produce a valuable hypothesis.
Authorship therefore cannot substitute for evaluation.
The scientific value of an argument ultimately depends upon the quality of its reasoning, evidence, methodology and capacity to survive scrutiny.
Interestingly, arXiv’s own policy is compatible with this distinction. The repository does not prohibit authors from using AI tools in research. It permits such use when it is disclosed and the research satisfies its standards of scholarly interest and advancement of the field.
That is an important distinction.
AI assistance is not necessarily the problem. Unexaminable reasoning is.
From Content Moderation to Epistemic Governance
This brings us to a concept that deserves much greater attention:
Epistemic governance.
Governance is normally discussed in AI in terms of safety, privacy, bias, accountability and regulatory compliance.
Those are important.
But scientific AI introduces another governance problem:
How do we govern the production and evaluation of claims?
If machines can generate thousands or millions of plausible arguments, hypotheses and manuscripts, filtering those outputs only after they have been produced becomes increasingly difficult.
The solution cannot simply be larger armies of human reviewers.
That approach does not scale.
Instead, scientific communication may eventually need systems capable of examining the structure of reasoning itself.
For example, a scientific claim might be accompanied by an explicit chain showing:
Claim → Evidence → Method → Assumptions → Inference → Uncertainty → Falsification conditions
The objective would not be to allow AI to declare something “true.”
Get José. T Guevara’s stories in your inbox
Join Medium for free to get updates from this writer.
Quite the opposite.
The objective would be to make the reasoning behind a conclusion inspectable.
From Trust to Examinability
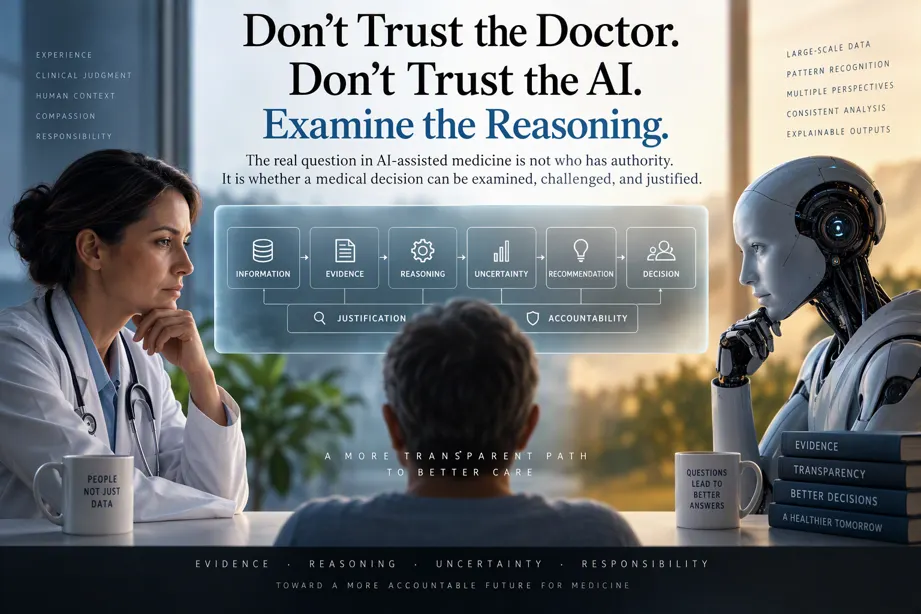
This connects with a broader problem I recently discussed in relation to AI and medical decision-making.
We often formulate the question incorrectly:
Should we trust human experts or the artificial intelligence?
There is another possibility.
We should increasingly ask whether the reasoning behind the decision can be examined.
Science faces the same problem.
Neither human authority nor artificial intelligence should become an epistemic black box.
Instead of asking only:
Who produced this conclusion?
we should also ask:
How was this conclusion produced?
What evidence supports it?
What assumptions were required?
What alternatives were considered?
What would demonstrate that the conclusion is wrong?
This is the transition from authority-based trust to examinable reasoning.
What AI Changes About Scientific Publishing
For centuries, publication itself functioned partly as a filter.
Producing papers was difficult.
Distributing them was difficult.
Reviewing them was difficult.
Those constraints limited volume.
AI destroys one of those constraints: production.
But it does not automatically solve the other constraint: evaluation.
This produces a profound imbalance.
When generating ten additional manuscripts becomes inexpensive but evaluating those manuscripts still requires expert human attention, scientific repositories inevitably encounter a scaling problem.
The arXiv figures may therefore represent something larger than a temporary moderation difficulty.
They may be an early indication of a structural transformation in knowledge production.
AI Could Be Part of the Solution
There is an irony here.
Artificial intelligence is contributing to the problem.
But artificial intelligence may also become part of the solution.
Not by replacing reviewers.
Not by deciding what is true.
And certainly not by becoming an automated gatekeeper of scientific thought.
Instead, AI could assist scientists by identifying the structure that must be examined.
An evaluation architecture could help expose:
- unsupported claims,
- missing evidence,
- inconsistent reasoning,
- hidden assumptions,
- citation dependencies,
- methodological gaps,
- contradictory conclusions,
- and uncertainty that has been presented as certainty.
Human experts would still make scientific judgments.
AI would help make the objects of those judgments easier to inspect.
That distinction is critical.
A New Bottleneck in Human Knowledge
The arXiv controversy should therefore not be understood simply as evidence that artificial intelligence is producing too many papers.
The deeper issue is this:
Human civilization may soon possess the ability to generate more plausible knowledge claims than humans can individually evaluate.
When that happens, the architecture of scientific communication must change.
The central problem becomes not merely information production.
It becomes epistemic filtration.
How do we preserve novelty?
How do we preserve falsifiability?
How do we preserve provenance?
How do we preserve accountability?
And above all:
How do we make reasoning examinable at scale?
That may become one of the defining scientific-governance problems of the AI era.
The crisis at arXiv is therefore worth watching carefully.
Because what appears today to be a problem of too many papers may actually be an early warning of something much larger:
We are approaching a world in which generating an argument is cheap, but determining whether that argument deserves to become knowledge remains expensive.
The future of scientific publishing may depend on closing that gap.
Author’s Note
This essay represents an independent analysis inspired by arXiv’s October 2026 announcement concerning submission growth, AI-assisted research and moderation pressure. The concepts of examinable reasoning and epistemic governance developed here are proposed as a broader framework for considering the problem rather than as positions attributed to arXiv. For more information about the solution, please contact me at: josetguevara108@outlook.es or josetguevara108@gmail.com